Fast fallback
Fast fallback runs a backup model alongside your primary model so a slow primary response does not have to hold up the conversation. It supports Retell-managed single-prompt, multi-prompt, and conversation-flow voice agents. Chat agents, custom LLM agents, and speech-to-speech models are not supported. Use it when your primary model usually works well but sometimes takes too long to respond. For example, an appointment-booking agent can use GPT 4.1 as its primary model and GPT 4.1 mini as its backup, with Fallback after set to 1.5 seconds. Test that both models follow the booking instructions and call tools correctly before deploying.How does the timeout work?
Both models start immediately. Fallback after is the time during which Retell prefers usable output from the primary model. If the primary has not started responding when that period ends, a ready backup can take over. If neither is ready, Retell still waits for usable output. If primary attempts fail, a ready backup can take over before the period ends. This setting is not a guaranteed response time. Model selection happens for each request; using a backup once does not switch the rest of the call permanently to that model. It is also separate from Response Wait time, which adds a deliberate pause after the caller stops speaking.Configure fast fallback
1
Open LLM settings
Open your voice agent and select the settings control beside its model selector. For a conversation flow, find this under Global settings → Agent settings.
2
Choose a backup model
Under Fallback model, select Fast fallback, then choose a model. Select its speed tier where available; the backup’s tier is independent of the primary’s.You can choose the same model as the primary. A different provider is not required.
3
Set the preference period
Adjust Fallback after, then select Confirm. New configurations default to 1.5 seconds. As of October 2026, the dashboard initially offers 0.3–3 seconds, with 0.1-second slider steps. A larger value already configured through the API expands the displayed range.
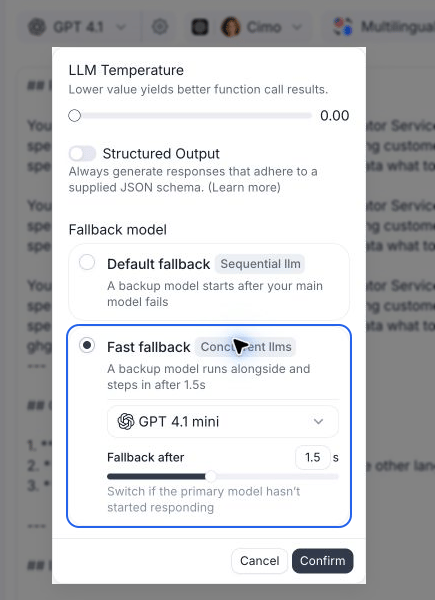
Choose Fast fallback, a backup model, and the primary preference period in LLM settings.
Fast fallback can incur charges for both models, including when only one response is used. Choose the backup and its tier with cost in mind; a lower timeout does not mean only the backup is billed.
Check which model was used
In Call History, open a call’s Transcription tab. An agent entry can show Fast fallback – [model] when a backup was used during the associated response. This can include a tool-only request within that response; it does not mean every displayed word was generated by the backup. See session history.Configure fallback through the API
Setmodel_config.backup on the Retell LLM or conversation flow used by your voice agent. The primary must be a text model (model_config.type: "cascading"). For the duplex type, which pairs the GPT Live voice model with a backend text LLM, the backup applies to that backend model.
These examples replace the backup on an existing voice agent’s response engine. Set the environment variables to your API key and the engine’s ID before running a command.
backup from an update preserves the saved backup. Supplying a backup object replaces that object, so include its model and any non-default tier or timeout you want to keep. Other omitted top-level model_config keys are preserved.
To remove the backup, set it to null:
Read fallback metadata
The Get Call response can includemetadata.backup_model_used on agent utterances in transcript_object and tool invocations in transcript_with_tool_calls. The object is optional; older calls and entries without recorded fallback use omit it.
These timings measure selection and readiness, not completed generation or end-to-end call latency. On an agent utterance, the object records the first backup used in its associated response, including tool-only requests. On a tool invocation, it identifies the backup used to generate that invocation.